
With the ear-mounted device, called C-Face, users could express emotions to online collaborators without holding cameras in front of their faces, which is an especially useful communication tool as much of the world engages in remote work or learning, said researchers at Cornell University.
With C-Face, avatars in virtual reality environments could express how their users are actually feeling, and instructors could get valuable information about student engagement during online lessons. It could also be used to direct a computer system, such as a music player, using only facial cues.
“In previous wearable technology aiming to recognize facial expressions, most solutions needed to attach sensors on the face,” said Zhang, director of Cornell’s SciFi Lab, “and even with so much instrumentation, they could only recognize a limited set of discrete facial expressions.”

Because it works by detecting muscle movement, C-Face can capture facial expressions even when users are wearing masks, Zhang said.
The device consists of two miniature RGB cameras – digital cameras that capture red, green and bands of light – positioned below each ear with headphones or earphones. The cameras record changes in facial contours caused when facial muscles move.
Once the images end up captured, they’re reconstructed using computer vision and a deep learning model. Since the raw data is in 2D, a convolutional neural network – an artificial intelligence model that can classify, detect and retrieve images – helps reconstruct the contours into expressions.
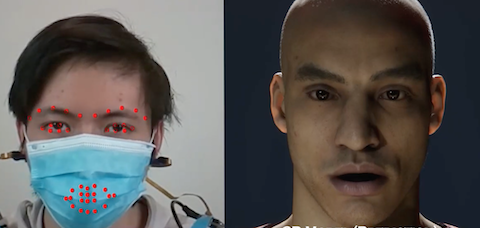
An earphone can continuously track full facial expressions by observing the contour of the cheeks, which can then translate expressions.
Cornell University screen capture
The model translates the images of cheeks to 42 facial feature points, or landmarks, representing the shapes and positions of the mouth, eyes and eyebrows, since those features are the most affected by changes in expression.
These reconstructed facial expressions represented by 42 feature points can also be translated to eight emojis, including “natural,” “angry” and “kissy-face,” as well as eight silent speech commands designed to control a music device, such as “play,” “next song” and “volume up.”
The ability to direct devices using facial expressions could be useful for working in libraries or other shared workspaces, for example, where people might not want to disturb others by speaking out loud. Translating expressions into emojis could help those in virtual reality collaborations communicate more seamlessly, said Francois Guimbretière, professor of information science and a co-author of the C-Face paper.
One limitation to C-Face is the earphones’ limited battery capacity, Zhang said. As its next step, the team plans to work on a sensing technology that uses less power.